Short answer: Give each device a retained status topic. When it connects, it registers a Last Will of offline and publishes online. The broker publishes the Will for it when nothing arrives for 1.5 × keepalive. Add an application heartbeat to catch devices that are connected but hung, and use a grace period (or the MQTT 5 Will Delay Interval) so short network blips don’t page anyone.
In this guide
- How keepalive and Last Will and Testament actually work, and why the Will sometimes never fires
- Production status topic design with retained messages
- MQTT 5 Will Delay Interval to remove false “offline” alerts
- Heartbeats that catch hung apps and silent reboots
- A Python watchdog with grace periods and site-outage grouping
- An ESP32 example with PubSubClient
Get the code: the watchdog and a set of failure scenarios (hung app, reboot, site outage, MQTT 5 Will Delay) are in the mqtt-iot-monitoring folder of ampaslabs/socketxp-blog-tutorials on GitHub. Run ./tests/run.sh hung and watch the alert arrive.
This is part of our MQTT IoT Monitoring guide, which covers the full self-hosted Mosquitto, Telegraf, InfluxDB and Grafana stack. This article goes deep on one problem: knowing reliably, and quickly, when a device stops working.
The Three Ways a Device “Goes Offline”
| Failure | Example | What catches it |
|---|---|---|
| Connection lost | Power cut, Wi-Fi drop, cellular dead zone, kernel panic | Keepalive + Last Will |
| Connected but hung | App deadlocked, sensor driver stuck, main loop blocked on I/O | Application heartbeat timeout |
| Silent reboot | Watchdog reset or brownout, back online within seconds | Uptime / boot counter in the heartbeat |
Most tutorials only cover the first row. In a real fleet, the second and third are common, and they’re the ones that go unnoticed for weeks.
How MQTT Keepalive and Last Will Work
When a device connects, the CONNECT packet carries two relevant settings:
- Keepalive (seconds): the longest the client promises to go without sending anything. If it has nothing to publish, it sends a tiny PINGREQ.
- Will message: a topic, payload, QoS and retain flag that the broker will publish on the client’s behalf if the client disappears.
The broker publishes the Will when:
- No packet arrives within 1.5 × keepalive. With
keepalive=60, that’s 90 seconds. - The network connection closes without a DISCONNECT packet, for example after a TCP reset or a crash of the client process.
- The broker closes the connection because of a protocol error.
The broker does not publish the Will when the client sends DISCONNECT. A clean shutdown discards the Will. This is the most common reason people report “my Last Will is not working”: the device shut down cleanly and so never announced it went offline.
Choosing a keepalive
| Link | Keepalive | Worst-case detection | Trade-off |
|---|---|---|---|
| Ethernet / Wi-Fi | 30–60 s | 45–90 s | Fast detection, negligible traffic |
| Cellular (LTE / NB-IoT) | 120–300 s | 3–7.5 min | Saves data and modem power |
| Battery / sleepy devices | Don’t hold a connection | Use expected-report timeout | See the sleepy devices section |
A PINGREQ/PINGRESP pair is only 4 bytes of MQTT data plus TCP/TLS overhead, so a 60-second keepalive costs very little on a powered device.
Status Topic Design
Use one retained status topic per device:
fleet/{site}/{device_id}/status → "online" | "offline" (QoS 1, retained)
The rules that make it reliable:
- Retain both values. A dashboard that starts up five minutes later still sees every device’s current state.
- Use QoS 1. Status changes are rare and must not be lost.
- Publish
onlinein theon_connectcallback, not just once at startup. The library reconnects automatically after a network drop, and the retainedofflineWill must be overwritten on every reconnect. - Keep the Will payload static. It’s fixed at connect time, so it can’t contain the time of death. Record the time on the subscriber side when the message arrives.
- Give every device a unique client ID. If two devices share a client ID, the broker disconnects one whenever the other connects. They kick each other off in a loop, which looks like constant flapping.
- Allow the Will topic in your ACL. If the device’s user isn’t allowed to publish to its status topic, Mosquitto silently drops the Will.
Python: Last Will with MQTT 3.1.1
This is the minimum correct device-side pattern, using paho-mqtt 2.x:
import os
import paho.mqtt.client as mqtt

DEVICE_ID = os.environ["DEVICE_ID"]
STATUS = f"fleet/{os.getenv('SITE', 'site1')}/{DEVICE_ID}/status"


def on_connect(client, userdata, flags, reason_code, properties):
    if not reason_code.is_failure:
        client.publish(STATUS, "online", qos=1, retain=True)


client = mqtt.Client(mqtt.CallbackAPIVersion.VERSION2, client_id=DEVICE_ID)
client.username_pw_set(DEVICE_ID, os.environ["MQTT_PASSWORD"])
client.will_set(STATUS, "offline", qos=1, retain=True)
client.on_connect = on_connect
client.connect(os.getenv("MQTT_HOST", "127.0.0.1"), 1883, keepalive=60)
client.loop_start()

# ... application work ...

def shutdown():
    # DISCONNECT discards the Will, so announce "offline" explicitly first
    client.publish(STATUS, "offline", qos=1, retain=True).wait_for_publish()
    client.disconnect()
    client.loop_stop()
Test it by pulling the network cable or running sudo kill -9 on the process, and watch from another machine:
mosquitto_sub -h broker.local -u watchdog -P "$WATCHDOG_PASSWORD" -t 'fleet/+/+/status' -v
# fleet/site1/device01/status online
# ... about 90 seconds after the cable is pulled ...
# fleet/site1/device01/status offline
MQTT 5: Debounce Flapping with Will Delay Interval
On Wi-Fi or cellular, a device can lose its connection for a few seconds many times a day. With plain MQTT 3.1.1, each blip publishes offline and then online straight after. That fills your status history with noise and can trigger false alerts.
MQTT 5 adds a Will Delay Interval. The broker waits that many seconds before publishing the Will. If the device reconnects to the same session in that time, the Will is never sent. Mosquitto has supported MQTT 5 since version 1.6.
There are two conditions to get right:
- The Session Expiry Interval must be at least as long as the Will delay. The Will is sent when the delay passes or the session ends, whichever comes first. With the default session expiry of 0, the session ends at disconnect and the Will goes out immediately.
- The device must reconnect with
clean_start=False. A clean start discards the old session, which also sends the Will right away.
import os
import paho.mqtt.client as mqtt
from paho.mqtt.packettypes import PacketTypes
from paho.mqtt.properties import Properties

DEVICE_ID = os.environ["DEVICE_ID"]
STATUS = f"fleet/{os.getenv('SITE', 'site1')}/{DEVICE_ID}/status"


def on_connect(client, userdata, flags, reason_code, properties):
    if not reason_code.is_failure:
        client.publish(STATUS, "online", qos=1, retain=True)


client = mqtt.Client(
    mqtt.CallbackAPIVersion.VERSION2,
    client_id=DEVICE_ID,
    protocol=mqtt.MQTTv5,
)
client.username_pw_set(DEVICE_ID, os.environ["MQTT_PASSWORD"])

# Wait 60 s before announcing "offline"; a quick reconnect cancels it
will_props = Properties(PacketTypes.WILLMESSAGE)
will_props.WillDelayInterval = 60
client.will_set(STATUS, "offline", qos=1, retain=True, properties=will_props)

# Keep the session alive longer than the Will delay
connect_props = Properties(PacketTypes.CONNECT)
connect_props.SessionExpiryInterval = 300

client.on_connect = on_connect
client.connect(
    os.getenv("MQTT_HOST", "127.0.0.1"), 1883,
    keepalive=60, clean_start=False, properties=connect_props,
)
client.loop_start()
The trade-off is slower detection. A real outage is now reported after up to 1.5 × keepalive + Will delay, which is 90 + 60 = 150 s with these settings. For most fleets that’s a good deal: an alert two minutes late is better than ten false alarms a day.
Still on MQTT 3.1.1? You can get the same effect on the subscriber side. Treat offline as pending, and only alert if no online arrives within the grace period. The watchdog below does exactly that.
Heartbeats: Catching Hung Apps
Keepalive pings come from the MQTT library’s network thread (loop_start() in Python, or the client task in ESP-IDF). If your application’s main loop deadlocks, that thread keeps answering pings. The broker sees a healthy client, and the Will never fires.
The fix is a heartbeat published from the main application loop, after the real work succeeds:
import json
import time
import psutil

HEARTBEAT = f"fleet/{SITE}/{DEVICE_ID}/heartbeat"
INTERVAL = 30

while True:
    reading = read_sensors()          # your real work; if this hangs, heartbeats stop
    publish_telemetry(reading)
    client.publish(HEARTBEAT, json.dumps({
        "uptime": int(time.time() - psutil.boot_time()),
        "interval": INTERVAL,
    }), qos=0)
    time.sleep(INTERVAL)
Two details make the heartbeat much more useful:
uptimeshows reboots. If the new value is lower than the last one, the device restarted, even if it was back within seconds and the Will never fired.intervallets the watchdog work out the timeout per device, so devices on different schedules can share one watchdog.
If you already publish telemetry on a fixed schedule from the main loop, the telemetry message can act as the heartbeat. Just add the uptime and interval fields to it.
A timeout of three missed intervals is a sensible default. It tolerates one or two lost QoS 0 messages without paging anyone.
A Production Offline Watchdog
This watchdog combines all three signals and adds two things a simple version lacks:
- A grace period:
offlineand missed heartbeats only alert if the device doesn’t recover withinGRACEseconds. - Site grouping: if most devices at one site go down together, it sends one site-outage alert instead of fifty device alerts.
import json
import os
import threading
import time
from collections import defaultdict

import paho.mqtt.client as mqtt

GRACE = 60            # seconds a problem must last before we alert
MISSED_BEATS = 3      # heartbeats missed before a device counts as stale
SITE_OUTAGE = 0.5     # share of a site's devices down at once = site outage

devices = {}          # "fleet/site/dev" -> state dict
lock = threading.Lock()


def alert(client, topic, state, reason):
    event = {"target": topic, "state": state, "reason": reason, "ts": int(time.time())}
    client.publish(f"{topic}/alerts", json.dumps(event), qos=1)
    print("ALERT", event)     # forward to Slack / PagerDuty / webhook here


def device(base):
    return devices.setdefault(base, {
        "last_beat": time.time(), "interval": 30, "uptime": None,
        "down_since": None, "alerted": False,
    })


def on_connect(client, userdata, flags, reason_code, properties):
    client.subscribe([
        ("fleet/+/+/heartbeat", 0),
        ("fleet/+/+/telemetry", 0),   # telemetry on a fixed schedule doubles as the heartbeat
        ("fleet/+/+/status", 1),
    ])


def on_message(client, userdata, msg):
    base, kind = msg.topic.rsplit("/", 1)
    now = time.time()
    with lock:
        d = device(base)
        if kind in ("heartbeat", "telemetry"):
            try:
                beat = json.loads(msg.payload)
            except ValueError:
                return
            uptime = beat.get("uptime")
            if uptime is not None and d["uptime"] is not None and uptime + 5 < d["uptime"]:
                alert(client, base, "rebooted", f"uptime reset to {uptime}s")
            d.update(last_beat=now, uptime=uptime, interval=beat.get("interval", 30))
            if d["alerted"]:
                alert(client, base, "recovered", "heartbeat resumed")
            d.update(down_since=None, alerted=False)
        elif kind == "status" and msg.payload == b"offline" and d["down_since"] is None:
            d["down_since"] = now   # pending; confirmed by the check loop after GRACE


def check(client):
    now = time.time()
    by_site = defaultdict(list)
    with lock:
        for base, d in devices.items():
            stale = now - d["last_beat"] > MISSED_BEATS * d["interval"]
            if stale and d["down_since"] is None:
                d["down_since"] = now
            down = d["down_since"] is not None and now - d["down_since"] >= GRACE
            by_site[base.rsplit("/", 1)[0]].append((base, d, down))

        for site, members in by_site.items():
            new = [(b, d) for b, d, down in members if down and not d["alerted"]]
            if not new:
                continue
            down_count = sum(1 for _, _, down in members if down)
            if len(members) >= 4 and down_count / len(members) >= SITE_OUTAGE:
                alert(client, site, "site-outage", f"{down_count}/{len(members)} devices down")
            else:
                for base, _ in new:
                    alert(client, base, "offline", "no heartbeat or Last Will received")
            for _, d in new:
                d["alerted"] = True


client = mqtt.Client(mqtt.CallbackAPIVersion.VERSION2, client_id="offline-watchdog")
client.username_pw_set("watchdog", os.environ["MQTT_PASSWORD"])
client.on_connect = on_connect
client.on_message = on_message
client.connect(os.getenv("MQTT_HOST", "127.0.0.1"), 1883, keepalive=60)
client.loop_start()

while True:
    check(client)
    time.sleep(10)
The watchdog’s MQTT user needs read access to fleet/# and write access to the alerts topics. Site alerts are published to fleet/{site}/alerts, so allow that too:
user watchdog
topic read fleet/#
topic write fleet/+/+/alerts
topic write fleet/+/alerts
Two operational notes:
- The watchdog itself can fail. Run it under systemd with
Restart=always, and give it its own Last Will onmonitoring/watchdog/statusso something else (Grafana, or an uptime check) notices if it disappears. - Restarting the watchdog resets its memory. It re-reads the retained statuses on startup, so a device that is still
offlinealerts once more after the grace period. If you’d rather suppress repeats, or need alert history, persist the state in InfluxDB or Redis.
Getting a Fleet Snapshot from Retained Status
Because every status message is retained, one command gives you the current state of the whole fleet:
# Print every device's retained status, then exit after 3 seconds of silence
# (-W prints "Timed out" to stderr and exits with code 27; that's expected)
mosquitto_sub -h broker.local -u watchdog -P "$WATCHDOG_PASSWORD" \
  -t 'fleet/+/+/status' -v -W 3

# Count offline devices
mosquitto_sub -h broker.local -u watchdog -P "$WATCHDOG_PASSWORD" \
  -t 'fleet/+/+/status' -v -W 3 | grep -c ' offline$'
When you decommission a device, clear its retained status by publishing an empty retained message. Otherwise it shows as offline forever:
mosquitto_pub -h broker.local -u admin -P "$ADMIN_PASSWORD" \
  -t 'fleet/site1/device07/status' -r -n
ESP32: Last Will with PubSubClient
On microcontrollers the pattern is the same. With the Arduino PubSubClient library, the Will goes into connect():
#include <WiFi.h>
#include <PubSubClient.h>

const char* DEVICE_ID = "esp32-node-01";
const char* STATUS    = "fleet/site1/esp32-node-01/status";

WiFiClient net;
PubSubClient mqtt(net);

void connectMqtt() {
  while (!mqtt.connected()) {
    // connect(id, user, pass, willTopic, willQos, willRetain, willMessage)
    if (mqtt.connect(DEVICE_ID, DEVICE_ID, MQTT_PASSWORD, STATUS, 1, true, "offline")) {
      mqtt.publish(STATUS, "online", true);   // retained
    } else {
      delay(5000);
    }
  }
}

void setup() {
  WiFi.begin(WIFI_SSID, WIFI_PASS);
  while (WiFi.status() != WL_CONNECTED) delay(500);
  mqtt.setServer(MQTT_HOST, 1883);
  mqtt.setKeepAlive(60);
}

void loop() {
  connectMqtt();
  mqtt.loop();
  // publish the heartbeat from here, after real work, using millis() / 1000 as uptime
}
Note that PubSubClient publishes only at QoS 0, although the Will itself can be QoS 1. For TLS or mTLS on the ESP32, swap WiFiClient for WiFiClientSecure. See ESP32 mTLS Client Certificate Tutorial.
Sleepy and Battery-Powered Devices
Devices that deep-sleep between readings disconnect on purpose. If they keep a Last Will, every sleep cycle looks like an outage. For these devices:
- Don’t use the
online/offlineWill pattern. Connect, publish, disconnect cleanly, then sleep. - Report the next expected check-in in each message, for example
{"battery": 3.71, "next_report_s": 900}. - Alert on a missed check-in. The watchdog’s
intervalfield already handles this. Set it to the sleep period, and the device is flagged after three missed wake-ups. - Include battery voltage. It’s the best early warning of the most common way sleepy devices die.
What We Measured
We ran every scenario against Mosquitto 2.1.2 in Docker, with keepalive=60, a 60-second watchdog grace period and a 10-second check loop:
| Scenario | How we simulated it | What the broker / watchdog did | Time |
|---|---|---|---|
| Clean shutdown | docker stop (SIGTERM) | Agent published offline itself | Immediate |
| Process crash | docker kill (SIGKILL) | Broker published the Last Will (socket closed, no DISCONNECT) | Immediate |
| Frozen device / dead link | docker pause (no packets at all) | Broker published the Last Will after the keepalive expired | 87 s |
| App hung, connection alive | Main loop stops, network thread keeps pinging | No Last Will; heartbeat watchdog alerted | 95 s after the hang |
| Reboot | Uptime dropped from 86400 to 12 | rebooted alert | Immediate |
| Site outage | 4 devices at one site dropped together | One site-outage alert (“4/4 devices down”) | 66 s |
| Wi-Fi blip, MQTT 5 | Dropped for 8 s with a 20 s Will Delay | No offline published | n/a |
| Real outage, MQTT 5 | Dropped and stayed down | offline published once | 21 s (Will Delay 20 s) |
| Gateway lost internet | Killed the Pi gateway’s bridge | Bridge topic went 0; the ESP32’s status stayed online; heartbeat watchdog flagged it | Bridge: immediate |
Two results are worth calling out. The hung-app case is invisible to Last Will, so you do need the heartbeat. And an ESP32 behind a gateway keeps showing online on the central broker when the gateway loses its uplink, so you need both the bridge notification topic and the heartbeat timeout.
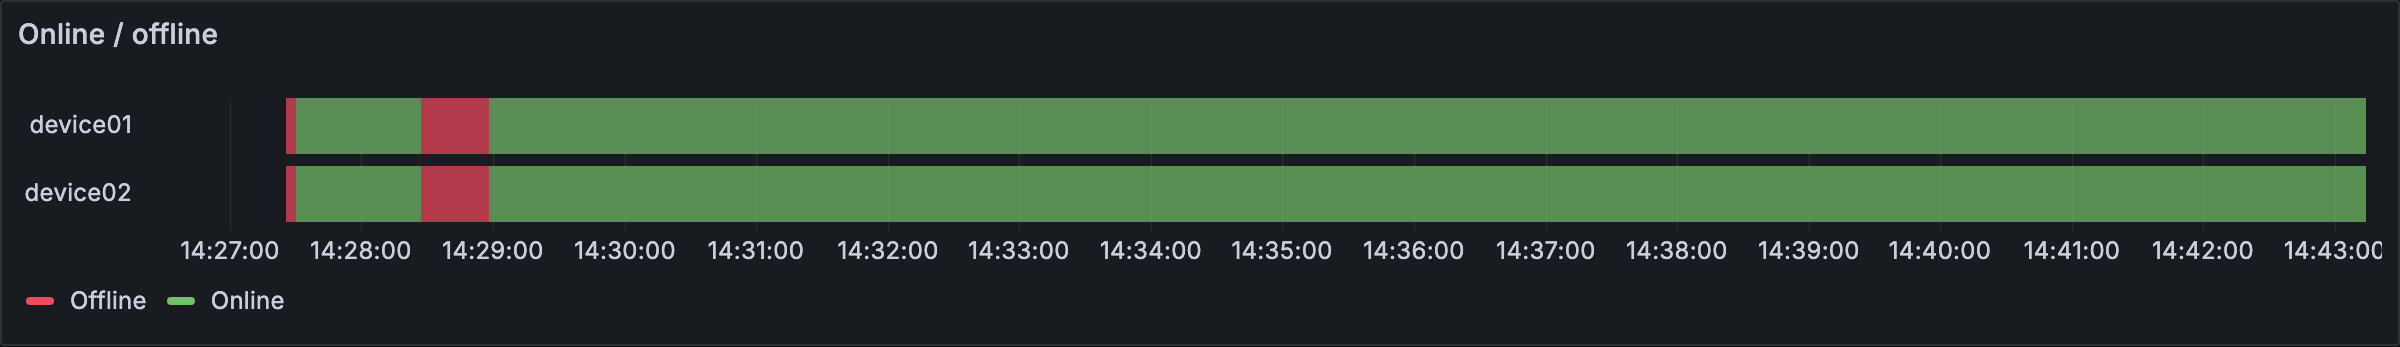
Online/offline history built from retained status and Last Will messages. The red blocks are two broker restarts during testing; both devices reconnected and reported online again within a minute.
You can rerun all of these with tests/run.sh in the companion code on GitHub.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| Will never fires | Clean DISCONNECT, or Will topic denied by ACL | Publish offline before disconnecting; allow the status topic in the ACL |
Device shows offline while it’s running | online published only at startup, not on reconnect | Publish online inside on_connect |
| Status flaps every few minutes | Duplicate client IDs, or an unstable link | Make client IDs unique; use Will Delay or a grace period |
offline arrives immediately, despite Will Delay | Session expiry is 0, or clean_start=True | Set SessionExpiryInterval ≥ Will delay and reconnect with clean_start=False |
| Detection takes several minutes | Long keepalive | Lower the keepalive, or accept the trade-off on cellular |
Decommissioned device stuck offline | Retained status never cleared | Publish an empty retained message to its status topic |
How SocketXP Complements MQTT Offline Detection
Detection is only half the job. Once the watchdog says device01 is hung or rebooting in a loop, someone has to diagnose and fix it, often on a device behind NAT, CGNAT or a cellular modem. MQTT can’t do that part. SocketXP is an IoT device management and remote access platform that picks up where the alert leaves off:
- Confirm what’s actually down. The SocketXP agent reports online/offline status and health alerts independently of MQTT. That lets you tell “the device is down” apart from “only the MQTT client is down”.
- Get onto the device. SSH in remotely, or use VNC, RDP or the browser terminal, without a VPN or port forwarding. Check
journalctl, copy logs off with SFTP, and restart the stuck service. - Fix every affected device, not just one. If a firmware or app bug is causing crash loops, push the fix as an OTA update to a pilot group first, then roll it out to the rest of the fleet. The watchdog’s
rebootedalerts stopping is your confirmation.
For a side-by-side view of what the MQTT stack does and what SocketXP adds, see How SocketXP complements your MQTT monitoring setup.
Next Steps
- The full stack this fits into: MQTT IoT Monitoring with Mosquitto
- Replace passwords with per-device certificates: MQTT mTLS Authentication Setup
Frequently Asked Questions
How does MQTT detect that a device is offline?
Through keepalive and Last Will and Testament (LWT). The device tells the broker its keepalive interval and a Will message when it connects. If the broker receives nothing from the device for 1.5 times the keepalive, or the TCP connection drops without a DISCONNECT packet, the broker publishes the Will message, typically 'offline' on the device's status topic.
Why is my MQTT Last Will not being sent?
The most common reason is a clean disconnect. When a client sends a DISCONNECT packet, the broker discards the Will without publishing it, so the device must publish 'offline' itself before disconnecting. Other causes: the keepalive is very long, the Will topic is not allowed by the broker ACL, or with MQTT 5 the Will Delay Interval has not expired yet.
How long does MQTT take to detect an offline device?
Up to 1.5 times the keepalive interval after the last packet. With keepalive=60 that is about 90 seconds. If you also use an MQTT 5 Will Delay Interval, add that delay. A broken TCP connection that the broker's operating system notices immediately (a TCP reset) triggers the Will faster.
Should the Last Will message be retained?
Yes. Publish both the Will 'offline' and the 'online' status with retain=true and QoS 1. Then any dashboard or service that subscribes later immediately gets each device's current status, without waiting for the next change.
Is Last Will enough to detect a failed IoT device?
No. If the application hangs but the MQTT library's network thread keeps running, it keeps answering keepalive pings and the Will never fires. Add an application-level heartbeat published from the main loop and alert when a device misses about three heartbeat intervals.
What is the MQTT 5 Will Delay Interval?
A property that tells the broker to wait a number of seconds before publishing the Will. If the device reconnects to the same session within that time, the Will is never sent. It removes false 'offline' alerts from short network blips. The session expiry interval must be at least as long as the Will delay, and the device must reconnect with clean_start=False.
How do I detect that an IoT device rebooted?
Include the device uptime (or a boot counter) in each heartbeat. If a new uptime value is lower than the previous one, the device restarted, even if it came back too quickly to trigger the Last Will.